Check it worked
What should be in Storage and Jobs once the pipeline runs, how to read a flow run, and the failures that actually happen.
Everything you built leaves a trace in two places: Storage holds the tables, Jobs holds every run that produced them. This page says what should be there, and what to do when it is not.
Where you are: the pipeline has run at least once, by hand or on its schedule.
What you should have
Section titled “What you should have”| What you built | What it does | Where it lives |
|---|---|---|
| Two HTTP configurations | bring the five files and the live forecast into the project | Components |
| SQL transformation | joins five of the six tables into staffing_outlook | Transformations |
| Data app | the grid anyone can open | Apps |
| Flow | runs all of it, in order, every morning | Flows |
Every job that ran is in Jobs; every table it touched is in Storage: two in.c- buckets
named after the connector and the configuration ID (keboola-ex-http-…), and one
out.c-Boolabean-staffing-outlook bucket.
The one number that proves the join
Section titled “The one number that proves the join”staffing_outlook should hold exactly 42 rows: six cafés times the seven days in the
forecast. Both inputs are fixed, so the count is too, and it catches both directions of failure:
- More than 42 means an input has duplicate rows: the forecast loaded twice with incremental
load switched on, or a café listed twice in
stores. The joins themselves cannot multiply rows; every band and every roster value is one row per café. - Fewer means a join dropped rows: a
location_idthat did not map onto astore_id, or a forecast that came back with fewer than seven days.
Open the table’s Data Sample and check the columns the right way round. store_name, city,
date, weekday, the two forecast columns and rostered_staff are filled on every row; they
come from straight lookups. expected_units and expected_units_per_person can be empty on a
row, and that is not an error: it means the summer never had a day in that café’s weather band, so
there is no history to average. In this sample the band with no history is cold and dry: five of
the six cafés never saw a dry day under 18 °C all summer, while cold, wet days happened everywhere.
short_handed is true on a few rows, never on all of them and rarely on none; our week had
four, and a cool, wet week can flag nothing, in which case the grid is right to be all quiet.
So the failure signals are the extremes: a lookup column empty on any row means a join matched
nothing, and expected_units empty on every row means the two band expressions in the SQL no
longer match each other. Column count is the second check: ten.
Reading a flow run
Section titled “Reading a flow run”The flow’s All Runs tab is the place to look: a duration chart over time, then a table of runs with who or what started them (your name for a manual run, scheduled run for the schedule), plus duration and status. Expand a run to see its phases.
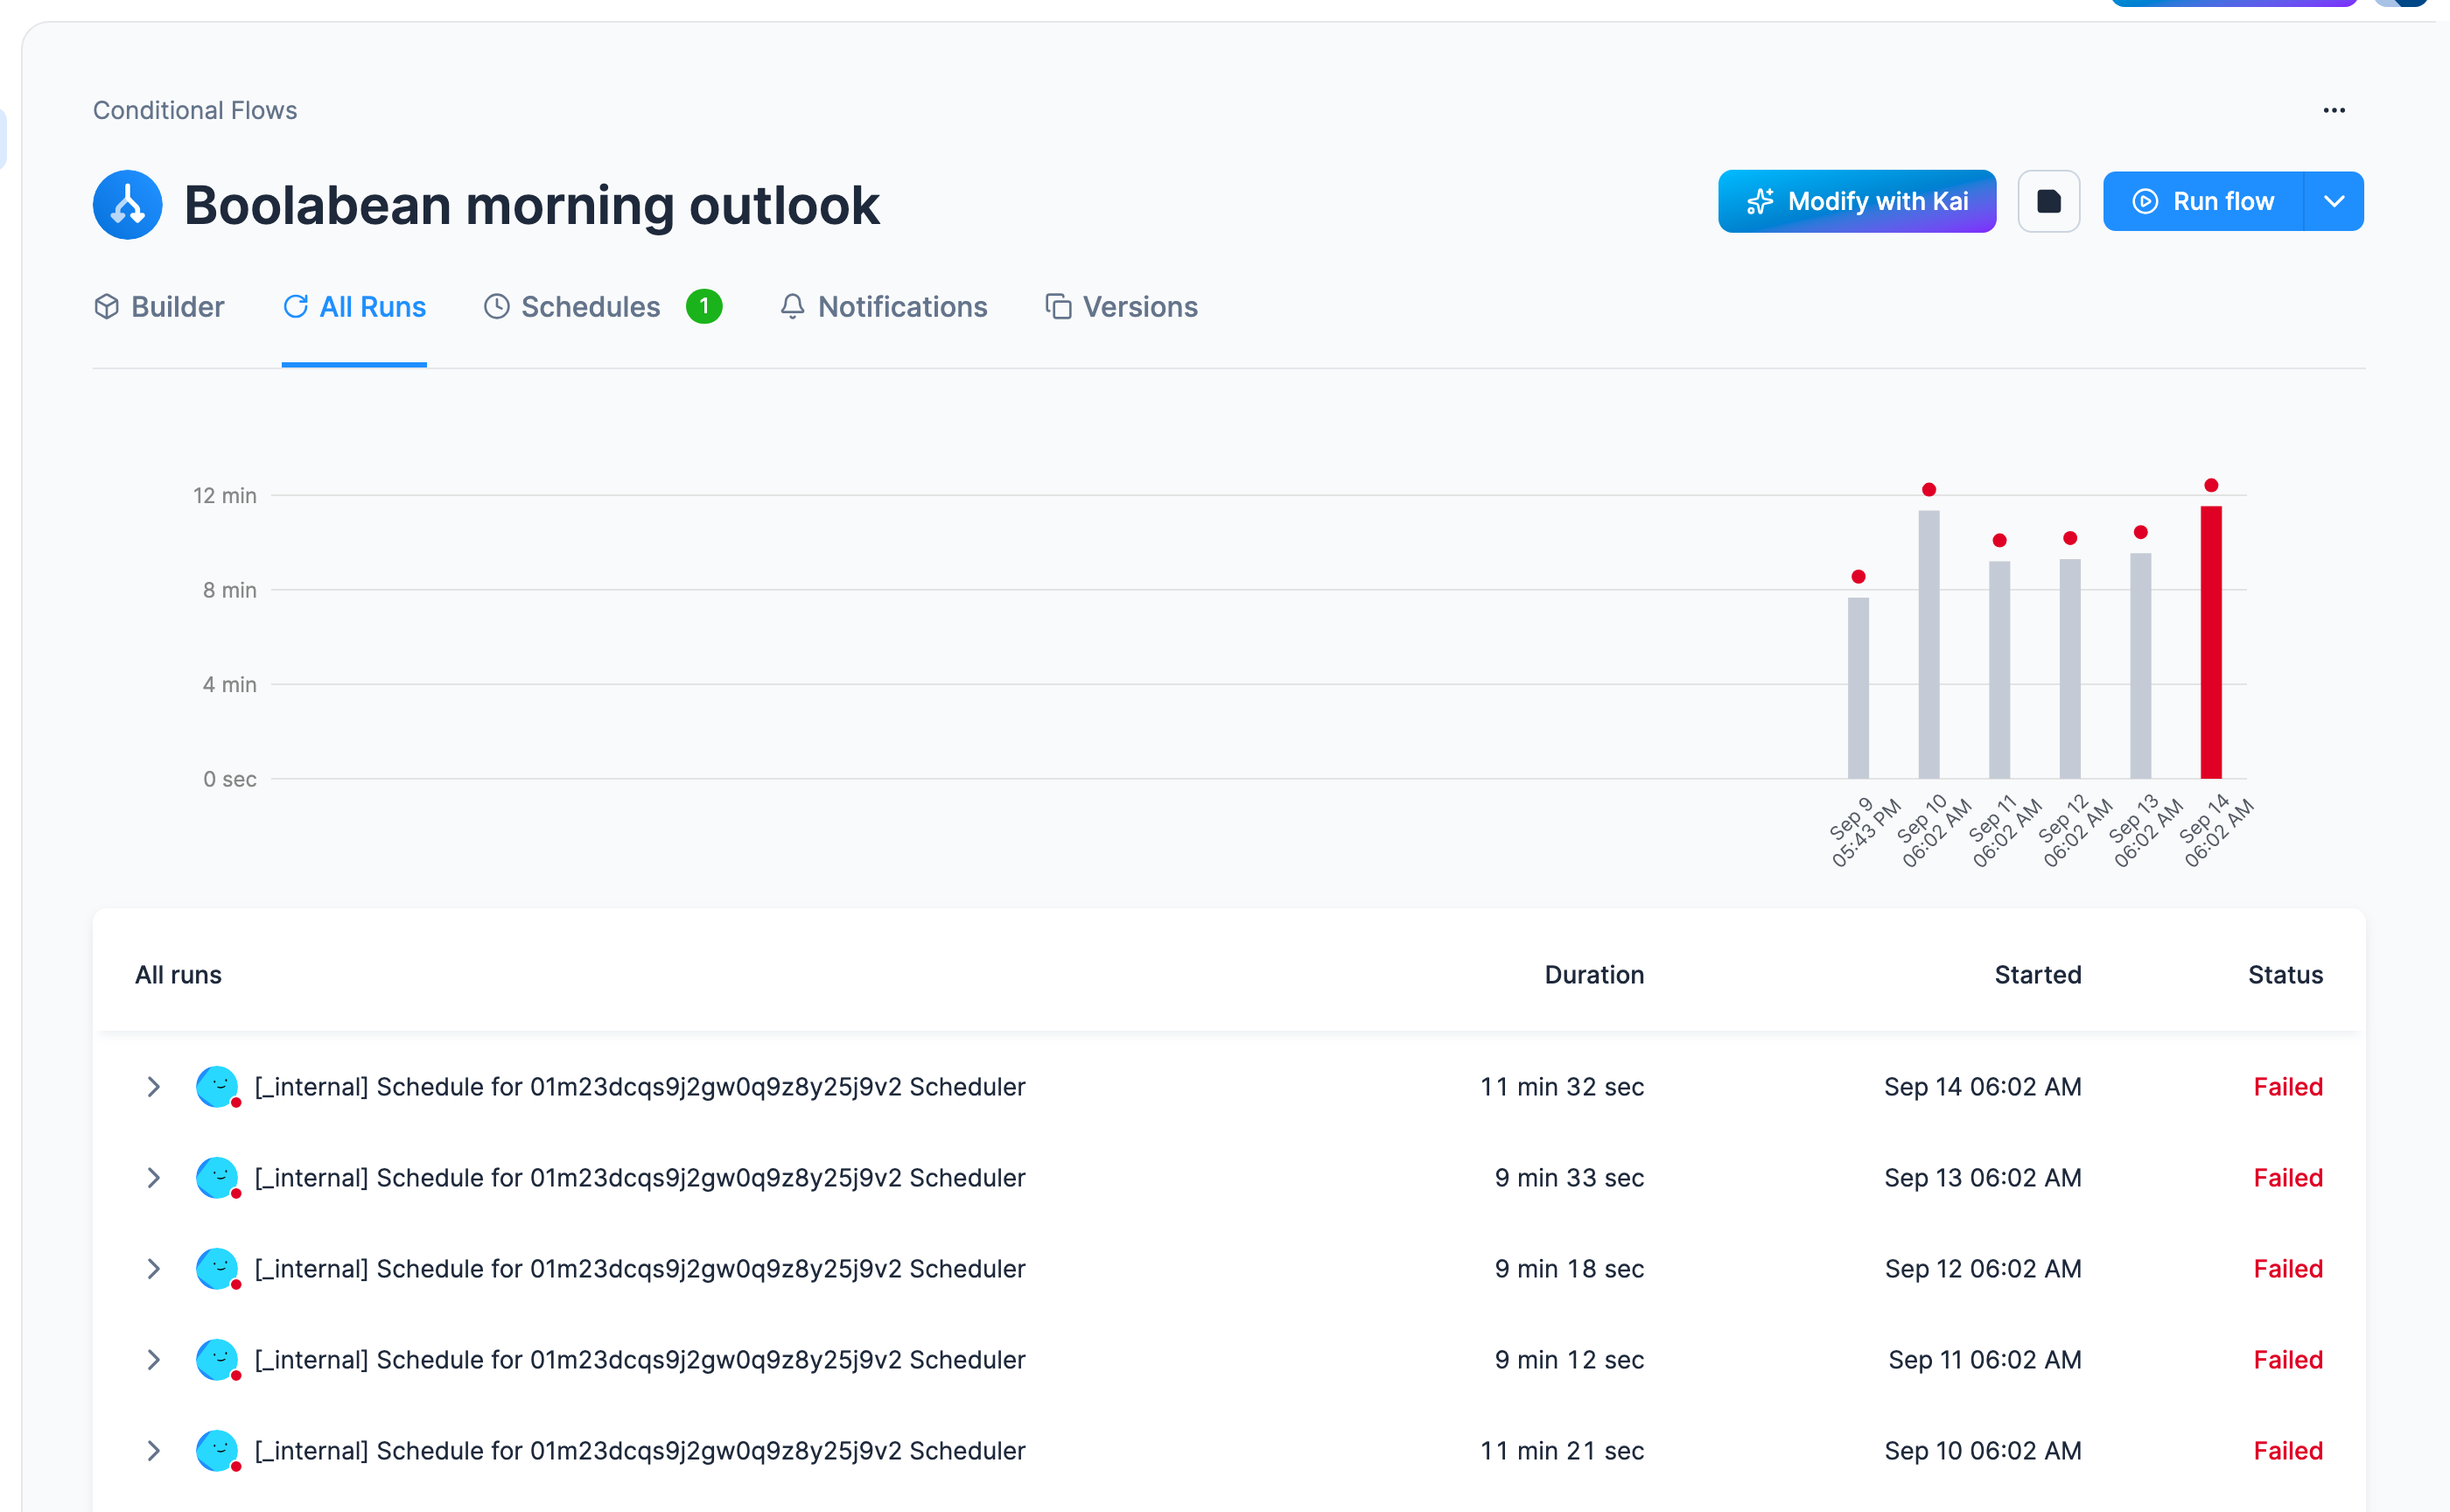
- A run with status Success is the goal. End to end this pipeline takes a few minutes: the two loads take about two minutes, the transformation under one, and the app deploy is the slow part.
- A run with status Error is not all lost. Phases run in order, so the phases before the
failed one have completed and their tables are updated. Our first run of the flow ended red at
the app phase while both data phases were green, and
staffing_outlookhad been rebuilt anyway. Read the run detail top to bottom and you know which step to look at, and which not to. - Jobs lists more entries than you might expect: a job per task, a Conditional Flows phase job per phase, the Conditional Flows job for the run itself, and for a row-based connector run from a flow a job per row under its task, so the five-file configuration alone shows as six lines. That is normal; the extra jobs are the ordering, not extra work.
- The Schedules tab shows a count, and a schedule can be toggled off without deleting it.
The same checks from a terminal
Section titled “The same checks from a terminal”Every number above has a read-only command behind it, which is the fastest way to answer “did last
night’s run work?” without opening the project. They need
kbagent connected to your project — docs-demo below is a project alias,
substitute yours:
kbagent job list --project docs-demo --component-id keboola.flow --limit 5kbagent job detail --project docs-demo --job-id <job-id>kbagent storage tables --project docs-demo --bucket-id out.c-Boolabean-staffing-outlookThe first prints the flow’s recent runs with their status and duration, the second opens one of them — including which task failed — and the third is the row count that proves the join. None of them changes anything.
The failures that actually happen
Section titled “The failures that actually happen”- The transformation fails inside the flow but works on its own. Its phase is running before the loads finish. Check that both connectors sit in an earlier phase, not the same one.
- Every task succeeds but the grid is unchanged. The app phase is missing from the flow, or the app was never deployed after it was published, so it still serves the old table. Read the run detail top to bottom: the phases run in the order shown, and an app that is not in the flow is not refreshed by it.
- The app phase fails and the rest succeeds. A deploy builds and starts a container, and it can fail for reasons that have nothing to do with your data. The table is already rebuilt; open the app’s page and start it again from there. The job’s own error is usually uninformative — Put it in front of someone shows how to read the container’s startup log, which is where the reason actually is. After several failed starts the platform disables the app (a banner says it failed to start automatically multiple times, and the button reads Start App), and the flow’s app phase will keep failing until someone starts it by hand. If the error repeats, that is one for Support with the job link.
- The forecast table has 42 rows but the outlook has more. Duplicate input rows: see the one number above.
- The scheduled run never happens. The schedule was saved but the flow is disabled, or the project is out of runtime credits.
- Jobs queue instead of running. Too many parallel tasks in one phase. Ten concurrent component jobs is the recommended ceiling; Support can adjust a project’s limits. Split the phase.
Failures specific to one step stay on that step’s page: loading problems on Get your data in, SQL and mapping problems on Transform data, delivery problems on Send a table to Google Sheets, and app problems on Put it in front of someone.